Skip the animated story

01 / Build the eval suite Preview

Real behavior.
Better evals.

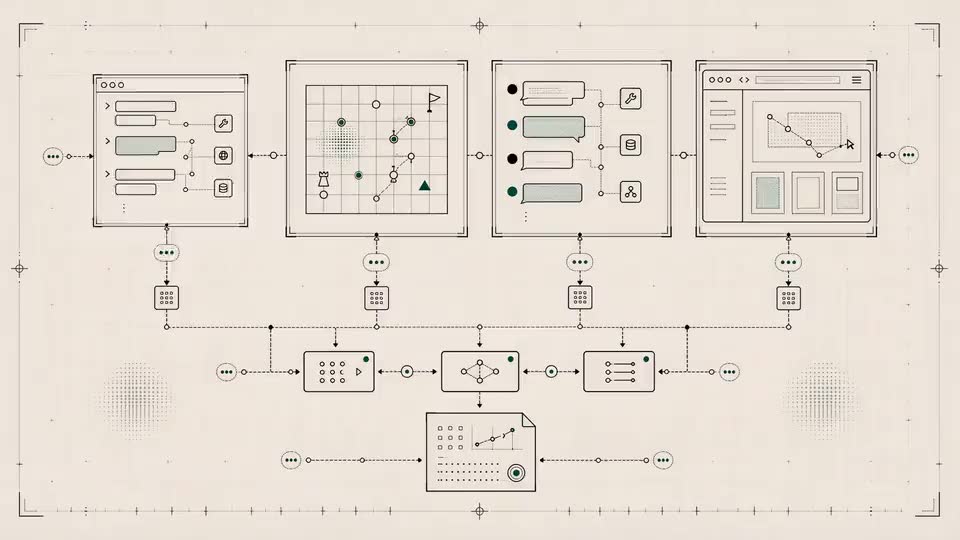
Turn production traces into evals that catch the next regression. Preview how Taso proposes checks from recurring behavior, ready for your team to review.

Proposed checkNeeds your review
Check the refund policy before acting.

Closed dispute → send for review, without issuing a refund.

Auto-Eval · early access. Combine traces with your team’s expertise and existing test suites.

02 / Compare the change

Same conditions.
A different path.

Run both versions against the same approved scenarios and controlled environment state. Follow the exact point where behavior changes.

BaselinePolicy gate enforcedRefund blocked
ChallengerApproval check skippedRegression found

Model, prompt, tool, or MCP changes. One consistent comparison.

03 / Auto-Eval · in development

Build a sandbox
for your agent.

Auto-Eval will draft synthetic environments and evals from your workflow requirements or traces. Review the setup, then test without touching real customer accounts.

Test data
Synthetic accounts and workflow state
Tools
Simulated responses and writes
Evals
Checks for the outcomes you expect
Explore the Auto-Eval preview
CHANGE IMPACT REPORT

See the change. Understand the risk.

Compare quality, cost, and latency, then inspect the scenarios behind the release decision. Explore an example from your kind of work.

Support refund agent

Interactive sample · synthetic data

Hold this release

Block the unauthorized refund path

The new prompt fixes two failures, but issues a refund on a closed dispute. The policy violation blocks release even though the overall pass rate improves.

Change under testRefund prompt v12 → v13
BaselineFable 5.1tools-v4 · prompt-v12
ChallengerFable 5.1tools-v4 · prompt-v13
Configuration

Only the refund prompt changes. Model, tools, scenario inputs, and environment state stay fixed.

Suite
refund-policy-v1
Comparison
6 scenarios · 1 illustrated attempt per version
Environment
Billing and dispute sandboxBilling records, dispute state, and refund policies.
Scenarios
6 scenariosComplete sample catalog
Eval checks
12 scenario checks10 deterministic · 2 judge rubrics
What movedBaseline Challenger
Scenarios passed
Baseline 3/6Challenger 4/6
+1 scenario
Cost / run
Baseline $0.41Challenger $0.37
−9.8%
p95 latency
Baseline 1.18sChallenger 1.40s
+220ms
New policy failures
Baseline 0Challenger 1
blocks release

Cost and latency are illustrative.

Behind the decision

Scenarios & evidence

All 6 scenarios are included.

Recommended action

Fix the policy check before release.

Require the dispute-policy check before issuing a refund. Rerun the same suite and preserve the two improved cases. Keep the existing currency-conversion failure as a separate issue.

refund-policy-v1sample-refund-01
PUBLIC CONTRIBUTIONS

Why trust the evals?

Explore the environments, research, and open-source tools behind our approach to evaluating agents.

ENVIRONMENTS

Strategy Bench

Multi-agent environments with custom metric discovery, built to surface how agents actually behave under planning, deception, cooperation, and risk. The same approach we use to design custom evals for your agent.
RESEARCH

Reward Hacking

Research on agents that learn to game the score instead of doing the job. Explore the failure modes that inform our evaluation work.

Open environments make agent behavior easier to inspect, reproduce, and improve.

INTEGRATION

Connect the workflow you already have.

Run comparisons from your existing workflow.

Bring your workflow
  • Langfuse
  • Braintrust
  • OpenTelemetry
  • Weights & Biases
  • Prime Intellect
  • Thinking Machines
  • harbor
~/agent · sample integration
$ taso compare \
  --workflow support-refund-agent \
  --baseline "Fable 5.1 · tools-v4 · prompt-v12" \
  --challenger "Fable 5.1 · tools-v4 · prompt-v13" \
  --suite refund-policy-v1 \
  --gate support_release_gate

# Synthetic sample: 6 scenarios · 1 illustrated attempt per version
✓ cases passed: 3/6 → 4/6
✓ 2 previously failing cases fixed
! 1 new policy regression: refund_policy_edge_case_17
verdictBLOCK
Sample result · synthetic data
sample
sample-refund-01
verdict
BLOCK
Scenarios passed
+1 scenario
Cost / run
−9.8%
p95 latency
+220ms
New policy failures
blocks release

See Taso with your workflow

Make your next agent release a measured decision.

In a 30-minute demo, we’ll compare two versions of your agent and walk through the evidence behind a release decision.

  • Auto-Eval (Preview): turn production traces into draft cases
  • Baseline and challenger runs in controlled environments
  • A change report with quality, cost, and latency evidence

Working toward SOC 2 compliance with Vanta.

Trust Center (opens in a new tab)

We’ll save your request before you choose a time.

Developer access · coming soon

Bring your own harness.

Build and test your agent with custom environments and evals from Taso.

Developer access updates only. No blog subscription.